


Set layerdrop to 0.0 (the model was trained without stochastic depth)
Browse filesThe Transformers config of this model has `"layerdrop": 0.1`, but the model was trained by NeMo without stochastic depth: the `model_config.yaml` in the `.nemo` file has no `stochastic_depth_drop_prob`, i.e. NeMo's default of 0.0. The Transformers conversion script ignored that setting, so the config got the `ParakeetEncoderConfig` default of 0.1 instead.
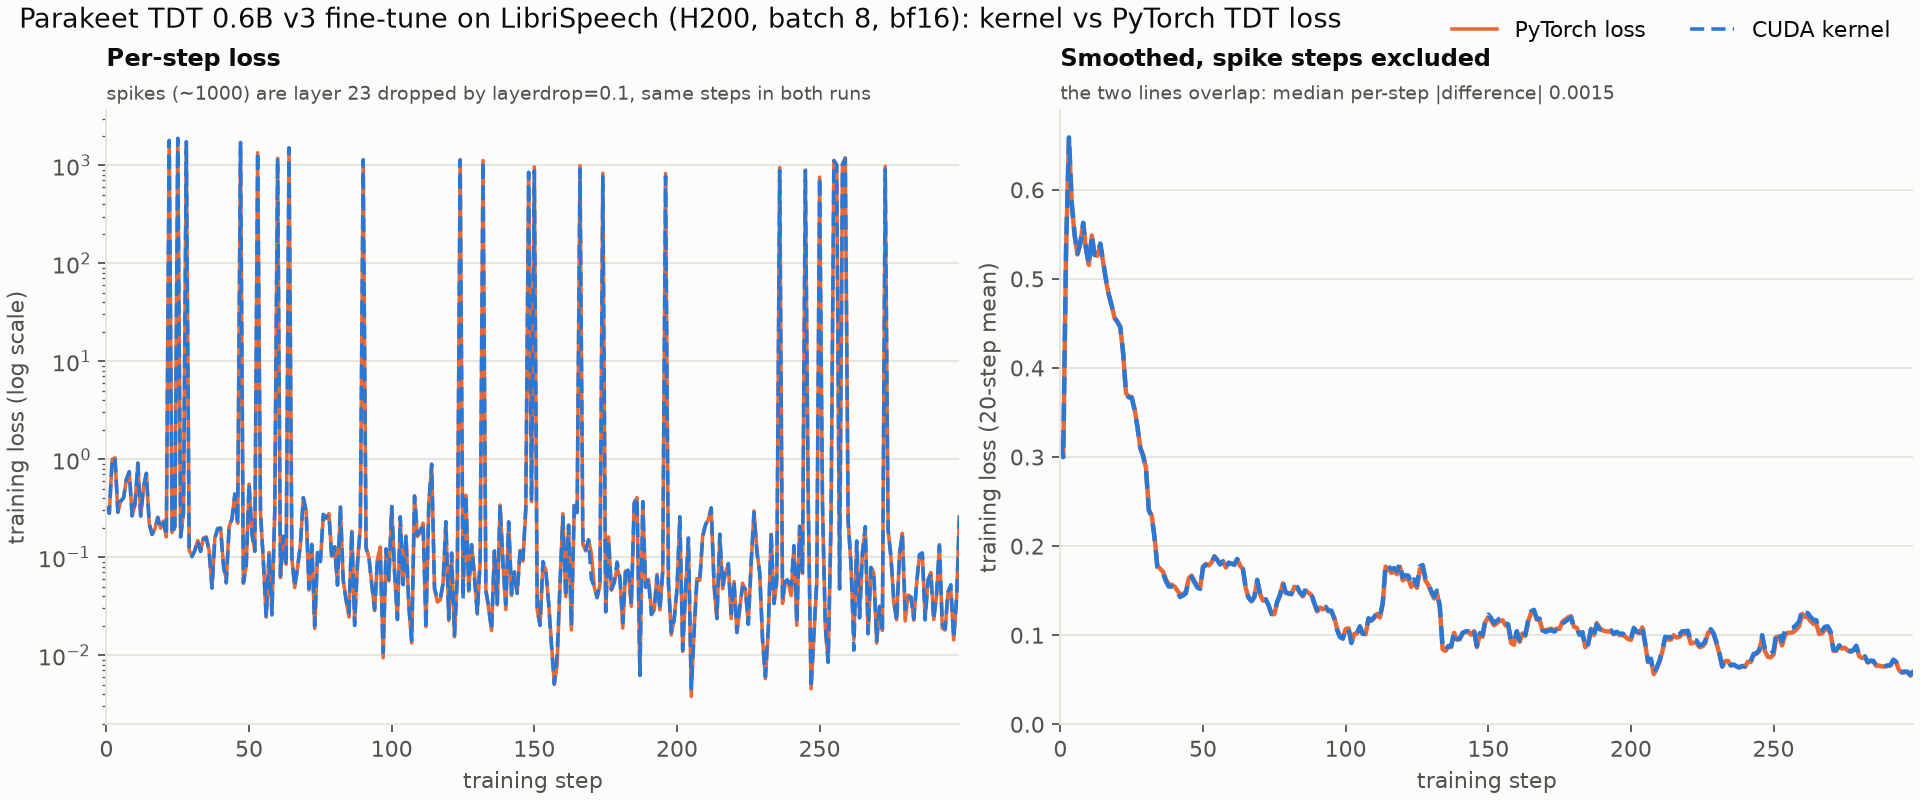
This only matters when fine-tuning with Transformers (layerdrop is disabled in eval mode), but there it breaks training: each encoder layer is skipped with probability 0.1, and skipping the **last** layer destroys the output. With `nvidia/parakeet-tdt-0.6b-v3`, skipping any one of layers 0-22 leaves the loss at ~0.3, while skipping layer 23 gives a loss of ~2000. In a 300-step fine-tune on LibriSpeech, 23 steps had losses of ~1000 and gradient norms of ~10⁴:
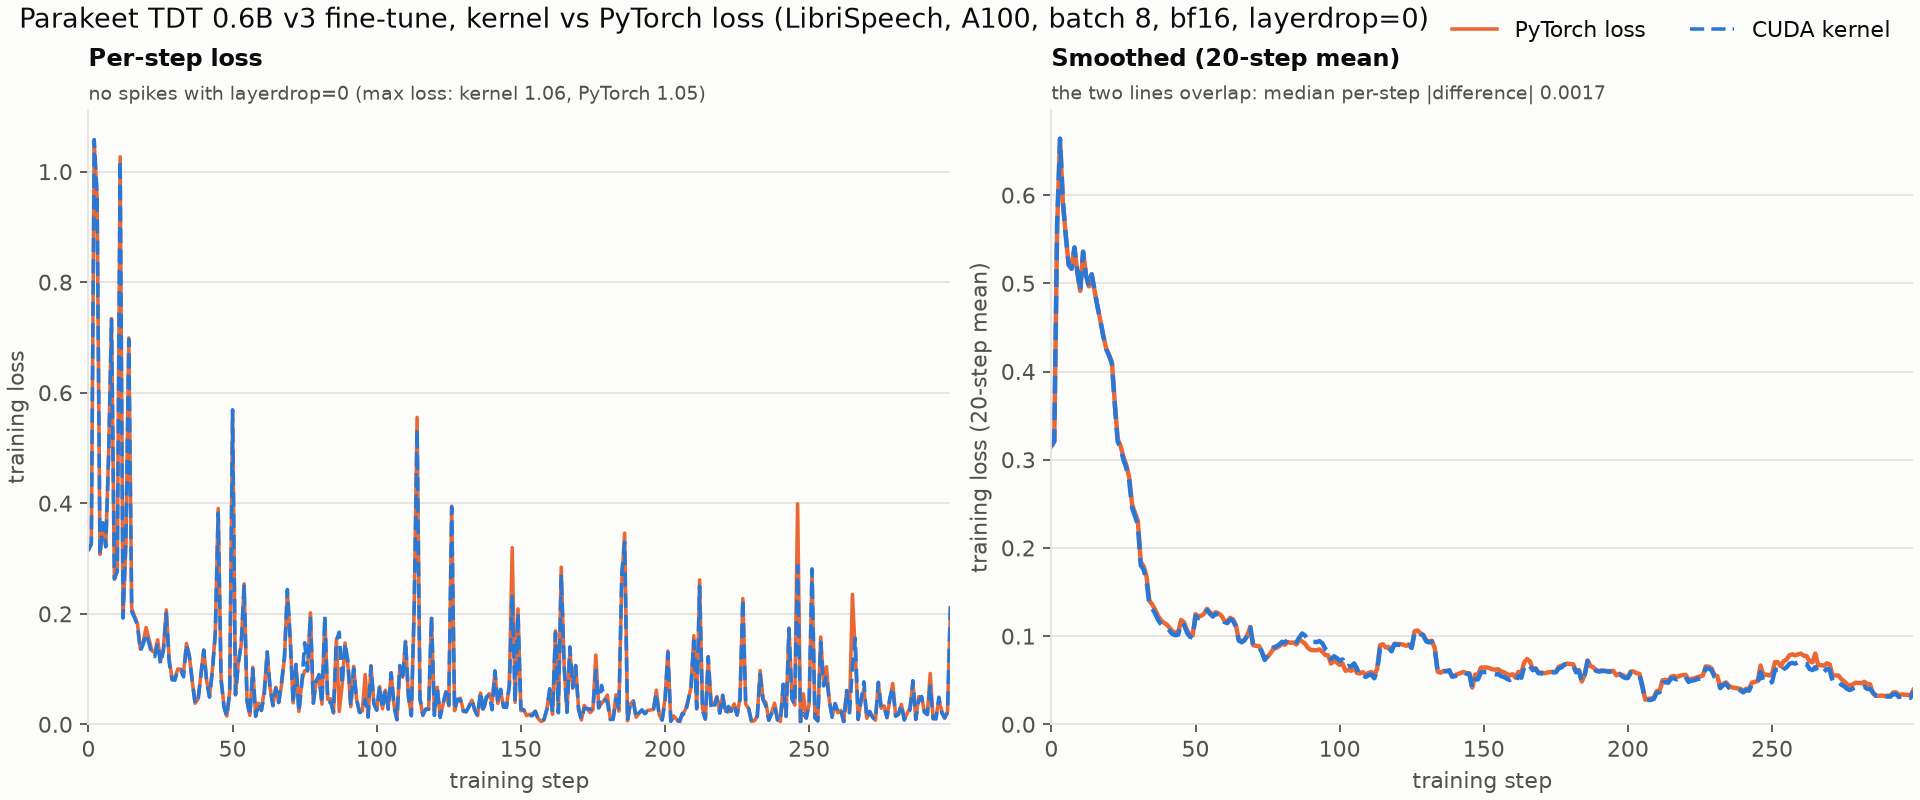
With `layerdrop` set to 0.0 there are no spikes (max loss 1.06), and the final loss is lower:
This PR sets `"layerdrop": 0.0` to match how the model was trained. Inference is unaffected. The conversion script is being fixed in Transformers so that new conversions keep NeMo's value.
- config.json +1 -1
|
@@ -17,7 +17,7 @@
|
|
| 17 |
"hidden_size": 1024,
|
| 18 |
"initializer_range": 0.02,
|
| 19 |
"intermediate_size": 4096,
|
| 20 |
-
"layerdrop": 0.
|
| 21 |
"max_position_embeddings": 5000,
|
| 22 |
"model_type": "parakeet_encoder",
|
| 23 |
"num_attention_heads": 8,
|
|
|
|
| 17 |
"hidden_size": 1024,
|
| 18 |
"initializer_range": 0.02,
|
| 19 |
"intermediate_size": 4096,
|
| 20 |
+
"layerdrop": 0.0,
|
| 21 |
"max_position_embeddings": 5000,
|
| 22 |
"model_type": "parakeet_encoder",
|
| 23 |
"num_attention_heads": 8,
|